
NEYSA TYTAN
GPU Clusters in India: High-Density Compute for AI Training
Deploy your AI on dedicated GPU clusters built on NVIDIA or AMD silicon, with the network interconnect of your choice. Our engineering team keeps your production runs stable.
Zero
Service interruptions or security breaches across 24 months
99.9% Availability
Contractual SLA maintained over six consecutive months
$1.2B Funding
Blackstone-led funding round securing the platform build-out
20,000+ Accelerators
Committed installation path through 2027


Why Neysa
Every cluster is engineered around the physics of your workload
We design infrastructure from the silicon up. The full stack is tightly integrated to meet the demands of AI model training and production inference.
Choice at every layer.
Your choice of accelerator, fabric, and storage, with the control plane and SLA built to your requirement.
Infrastructure that holds the line.
High-availability Active/Active or Active/Passive architecture with hot spares. A contracted GPU replacement commitment restores instances promptly.
Observability and deep monitoring.
Full-stack DCGM telemetry from the whole fleet down to each accelerator, across bare metal, Slurm and Kubernetes. See how GPU monitoring and ML observability works.
Operation and service assurance.
An India-based 24x7 NOC and SOC practice with a named technical account manager and a defined four-level escalation path.
Connectivity and network fabric.
Carrier-diverse uplink up to 100 Gbps, private Cloud Connect, and intelligent load balancing with health-checked failover.
Filesystems sized for the run.
Your choice of parallel filesystem over RDMA, WEKA, VAST or DDN, with S3-compatible object storage and persistent snapshots available.
“Their robust platform and continuous support allowed our team to focus squarely on the complexities of LLM development, significantly accelerating our progress in creating advanced AI capabilities for Indian languages.”
Rishi Bal
CEO
BharatGen (TIH, IIT Bombay)
17B Parameters
Param-2 mixture-of-experts architecture deployed in production
22 Trillion Tokens
Cumulative throughput sustained across the entire training run
Zero
Interrupted runs during massive-scale distributed training
"By partnering with Neysa, we have finally moved past the latency and cost barriers of legacy infrastructure to a system that handles our scale with total reliability."

Anil Porter
CIO
ITQ Technologies
141 Billion Tokens
Served every month across two production LLM services
14s to under 2s
P99 latency on live fare-rule and refund workloads
40% Lower TCO
Against the general-purpose cloud design it replaced
Available Compute
High-density 8-accelerator bare-metal deployments, tiered by term duration
Single-tenant hardware with local NVMe and a unified non-blocking fabric. Rates drop as your term grows, from 6 to 36 months. See GPU cloud pricing.
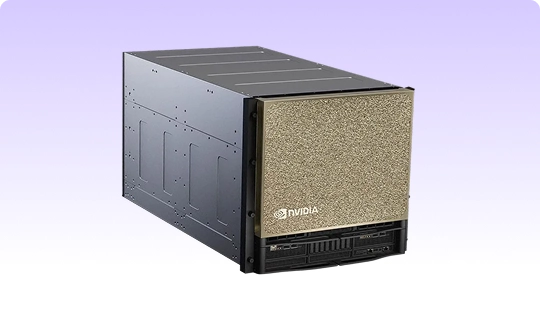
NVIDIA B300 GPU
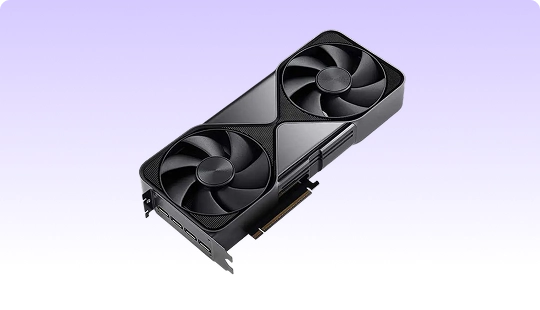
NVIDIA RTX PRO 6000
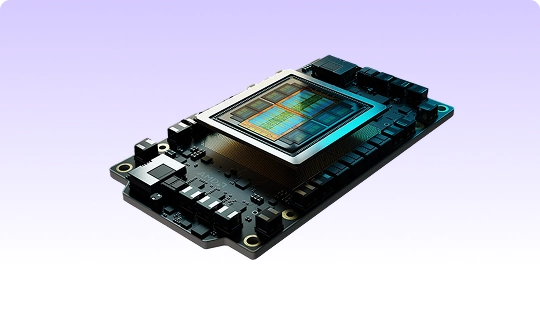
AMD Instinct MI350 GPU
Workload Orchestration
Deploy orchestration on your terms
Provision bare metal, initialize managed engines, or accept a turnkey Slurm environment.
Bare Metal For custom engineering stacks
- OS-level access allowing your own runtimes, drivers, and orchestration on the silicon
- Out-of-band management via BMC and Redfish API
- Private, single-tenant deployments with optional MIG or SR-IOV partitioning
Managed Kubernetes Engine For training and inference
- Managed control plane provisioned and maintained by Neysa
- Integrated Command Center for fleet health and expenditure visibility
Slurm Workload Manager For distributed training
- Turnkey cluster provisioning in standard configuration, delivered ready for production
- Direct SSH access to the cluster
Regulatory-grade assurance
Infrastructure engineered for trust
Keep full sovereignty over your model weights and production runs, backed by rigorous governance, defined accountability and AI infrastructure security.
 CSA Star
Level 2
 CSA TRUSTED
CLOUD PROVIDER
 SOC 2
 ISO
27001:2022
ISO27017:2015
ISO27018:2019
 DPDPA
READINESS
 INDIA AI MISSION
EMPANELMENT
FAQ