

If vLLM already solved LLM serving, why did SGLang appear?

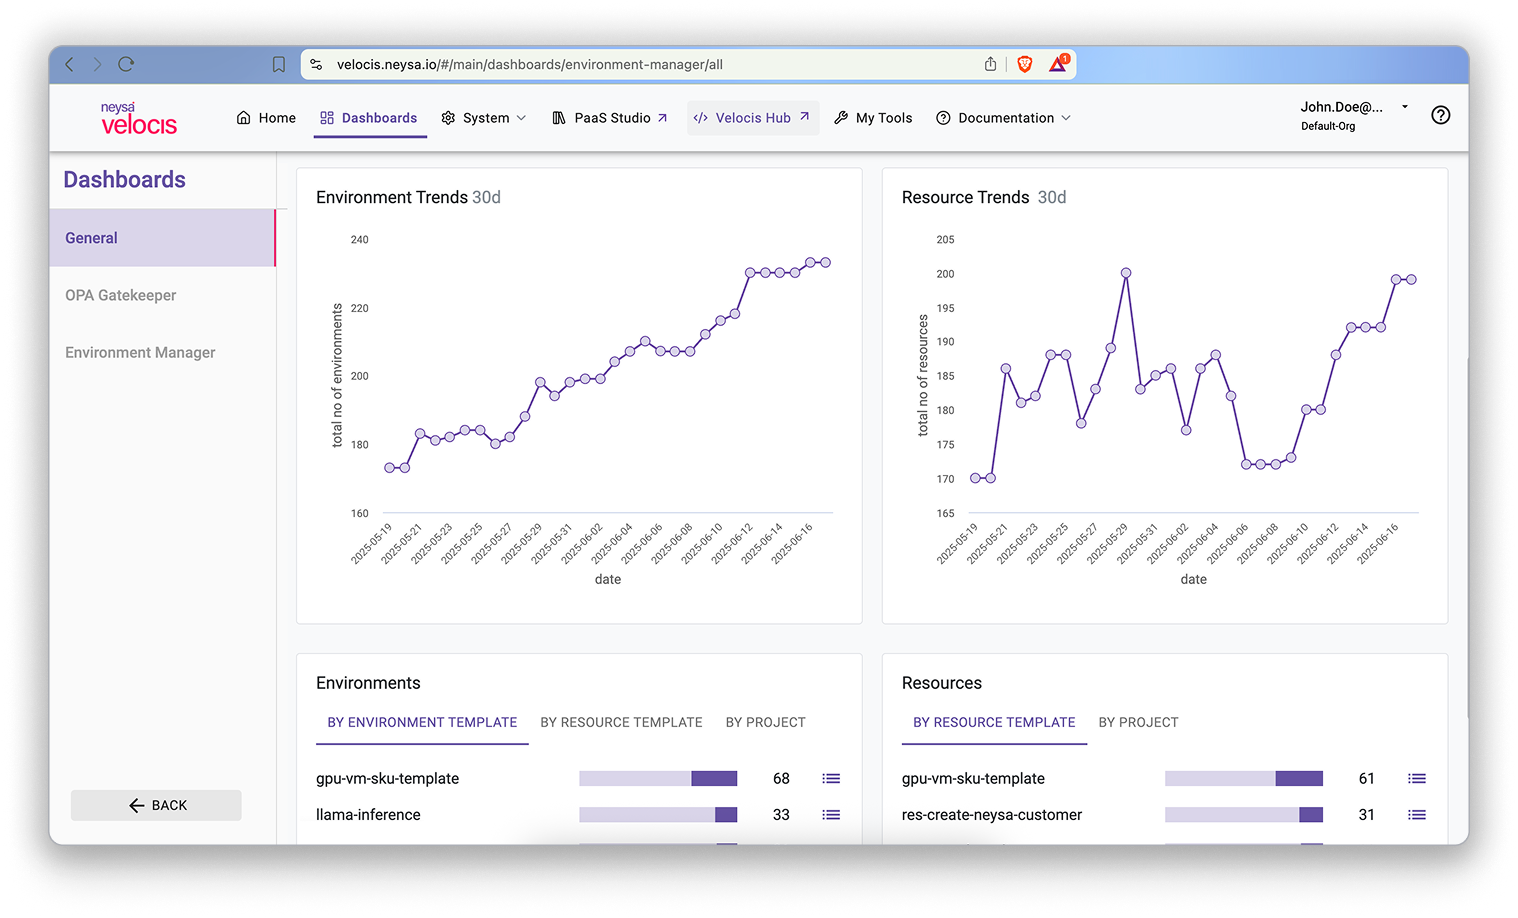
Access tools, frameworks, models and scalable GPU infrastructure to create and deploy AI use-cases with speed, ease and efficiency.

Run state-of-the-art VMs with NVIDIA GPUs: H100, L40S. Manage your distributed training with Kubernetes.
The most intuitive and resilient experience in setting up your ML/AI workload. High performance multi-cloud performance with just a few clicks.
Get on-demand access to scale capacity via a simple console request. With long-term reserve, you get discounts on resources.
01
Begin training, fine-tuning and prompt engineering with our Accelerated GPU Cloud built to meet your business demands.
02
Easily integrate your production applications using GlusterFS and Slurm to a full-scale distributed cluster using APIs of your choice.
03
With the fastest performance available
and elastic scaling, Neysa Velocis is built
to scale with your needs as you grow.
OUR PRICING PLAN
We offer on-demand GPUs at hourly rates for flexibility and monthly/annual commitments for cost savings. Explore our plans below:
| SKU description | No. of Instances |
Total Video Memory per SKU | On-Demand (INR) | 1-month (INR) | 6-month (INR) | 12-month (INR) |
|---|---|---|---|---|---|---|
|
NVIDIA L4
16 vCPU, 96GB RAM,
100GB NVME Inventory: 104
|
1
2
4
|
24GB
48GB
96GB
|
45.07
98.84
196.68
|
29.00
58.00
116.00
|
26.75
54.00
108.00
|
24.00
48.00
96.00
|
|
NVIDIA L40s
32 vCPU, 180GB RAM,
500GB NVME Inventory: 208
|
1
2
4
|
48GB
96GB
192GB
|
67.50
135.00
306.00
|
49.50
99.00
198.00
|
49.50
99.00
198.00
|
45.00
90.00
180.00
|
|
Cluster
NVIDIA H100 SXM
48 vCPU, 256GB RAM,
1000GB NVME Inventory: 392
|
1
2
4
8
|
80GB
160GB
320GB
640GB
|
153.00
306.00
612.00
1224.00
|
134.10
268.20
536.40
1072.80
|
125.10
250.20
500.40
1000.80
|
117.00
234.00
468.00
936.00
|
|
NVIDIA H100 NVL
48 vCPU, 256GB RAM,
1000GB NVME Inventory: 104
|
1
2
4
8
|
94GB
192GB
384GB
768GB
|
140.00
337.48
674.96
1349.92
|
135.00
294.44
588.88
1177.76
|
118.00
274.04
548.08
1096.16
|
100.00
257.08
514.16
1028.32
|
|
Cluster
NVIDIA H200 SXM
48 vCPU, 256GB RAM,
1000GB NVME Inventory: 200
|
1
2
4
8
|
141GB
282GB
564GB
1128GB
|
140.00
510.00
1020.00
1125.00
|
135.00
448.00
896.00
1100.00
|
118.00
418.00
836.00
945.00
|
100.00
390.00
780.00
785.00
|
|
AMD MI300
Inventory: 32
|
1
2
4
8
|
192GB
384GB
576GB
768GB
|
168.20
378.50
757.00
1416.50
|
165.04
371.35
742.70
1389.90
|
161.88
364.23
728.46
1363.20
|
148.00
333.00
666.00
1336.00
|
|
NVIDIA B200 SXM
|
1
2
4
8
|
192GB
384GB
576GB
768GB
|
323.00
646.00
1292.00
2584.00
|
308.00
616.00
1232.00
2464.00
|
293.00
586.00
1172.00
2344.00
|
279.00
558.00
1116.00
2232.00
|
|
NVIDIA B300 SXM
|
1
2
4
8
|
192GB
384GB
576GB
768GB
|
351.00
702.00
1404.00
2808.00
|
342.00
684.00
1368.00
2736.00
|
333.00
666.00
1332.00
2664.00
|
319.50
639.00
1278.00
2556.00
|
| Serial No. | Type | Price (in INR per GB/month) |
|---|---|---|
|
1
2
|
Ingress
Egress
|
0
0
|
| Serial No. | Type | Price (in INR per GB/month) |
|---|---|---|
|
1
2
|
High Speed Block Storage
Object Storage
|
9.3
9.3
|
Overall discount % offered for empanelment with IndiaAI – (10% – 15% range)
| Serial No. | Service Description | Price (in INR per month) |
|---|---|---|
|
1
|
Managed Kubernetes Service – Velocis Container Engine, non-HA (Single Master Node configuration)
|
2,45,000.00
|
|
2
|
Managed Kubernetes Service – Velocis Container Engine, HA
|
3,65,000.00
|
|
3
|
MLOps Platform – Full Deployment Capability, Incl. Access to Low Code No Code Tools
|
18,00,000.00
|
|
4
|
Premium Service and Support (24×7 Model) – Without Technical Account Manager
|
90,000.00
|
|
5
|
Premium Service and Support (24×7 Model) – With Dedicated Technical Account Manager
(60 Hours/Month)
|
2,70,000.00
|
|
6
|
AI/ML Expert (60 Hours/Month)
|
5,85,000.00
|
|
7
|
Velocis Advanced Cluster Manager (Per compute node or 8 AI compute units)
|
4,15,000.00
|
|
8
|
Velocis Advanced AI Job Scheduler (Per compute node or 8 AI compute units)
|
4,95,000.00
|
|
9
|
DevOps Engineer – 5 Days
|
13,50,000.00
|
|
10
|
Agentic AI developer – 5 Days
|
13,50,000.00
|
|
11
|
AI RAG Developer – 5 Days
|
13,50,000.00
|
| Type | Market Price (in INR per GB/month) |
|---|---|
|
Parallel File System
(Throughput – Minimum 1 GB/s read and 0.5GB/s write per AI Compute Unit)
|
9.3
|
| Type | Market Price (in INR per GB/month) |
|---|---|
|
Dedicated (MPLS) network
(Throughput – Minimum 1 GB/s)
|
50000
|
| Type | Market Price (in INR per GB/month) |
|---|---|
|
Internal NVMe/SSD storage
|
9.3
|
WHY NEYSA VELOCIS
Built for enterprises to use AI as much, as often, as easily and as cost efficiently as possible.
Efficient, consumption-based charging. Never pay for idle GPU time.
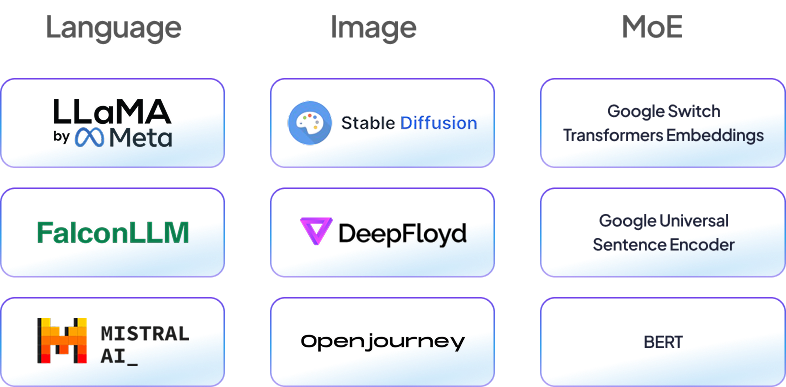
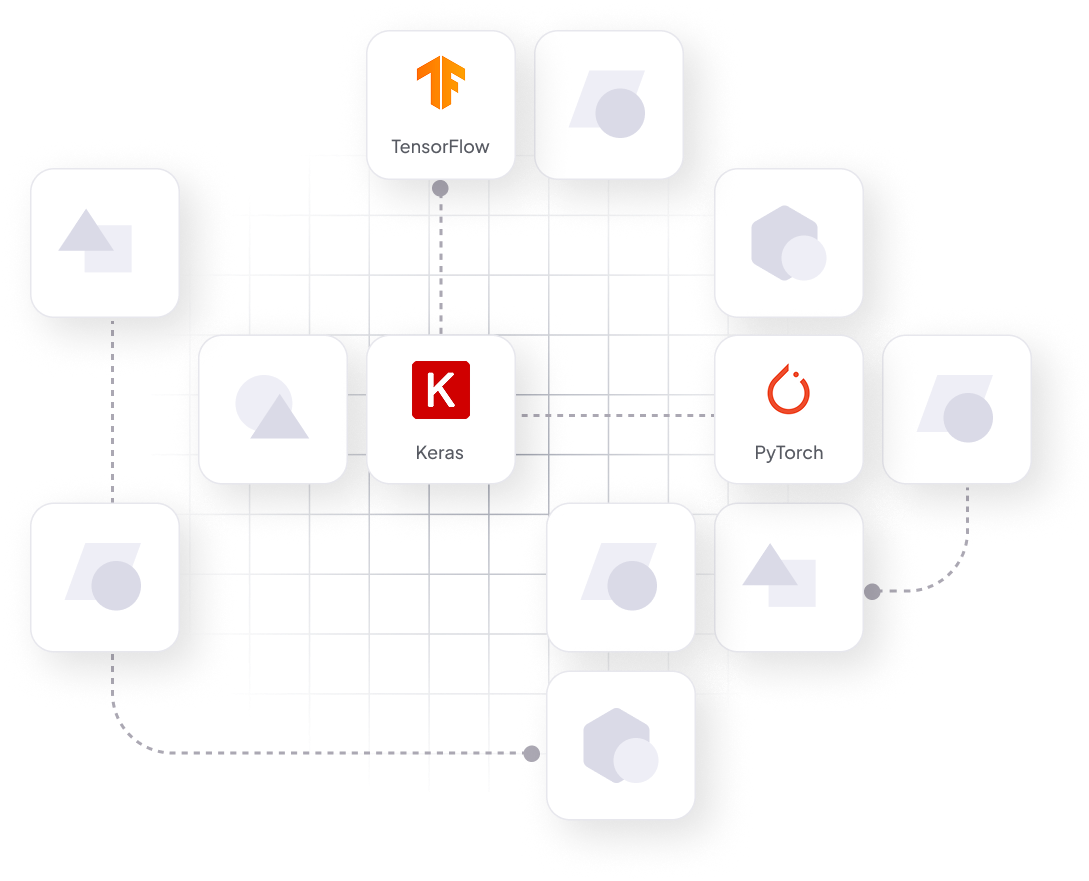
No lock-ins or painful migrations. Completely open-source & made to offer you choice at every layer.
No GPU hour wasted. Consumption-based charging ensures you never pay for more than you need or use.
Build and deploy your next real-world impact AI application with Neysa Velocis today.







